Measure & improve quality
Keep support quality high as your queue grows
Automatically review every case, human or AI, in one platform to spot quality gaps by product and issue and guide focused coaching.
Automatically review every case, human or AI, in one platform to spot quality gaps by product and issue and guide focused coaching.
Your technical support managers keep complex cases moving, handling escalations and supporting their teams. QA should help them understand how support is performing and where to focus, without adding more manual review.
See how support is performing across your entire queue—every product, every tier—while managers spend less time reading through cases and preparing for reviews.
Give managers and reps a consistent basis for feedback, with human and AI support measured against the same standards and clear reasons behind each score.
Find opportunities by product, issue or team, with specific cases to recognize good work, guide coaching, and flag recurring issues coaching can’t fix.
Share your scorecard or support standards, and we configure the criteria and weightings around how your team works.
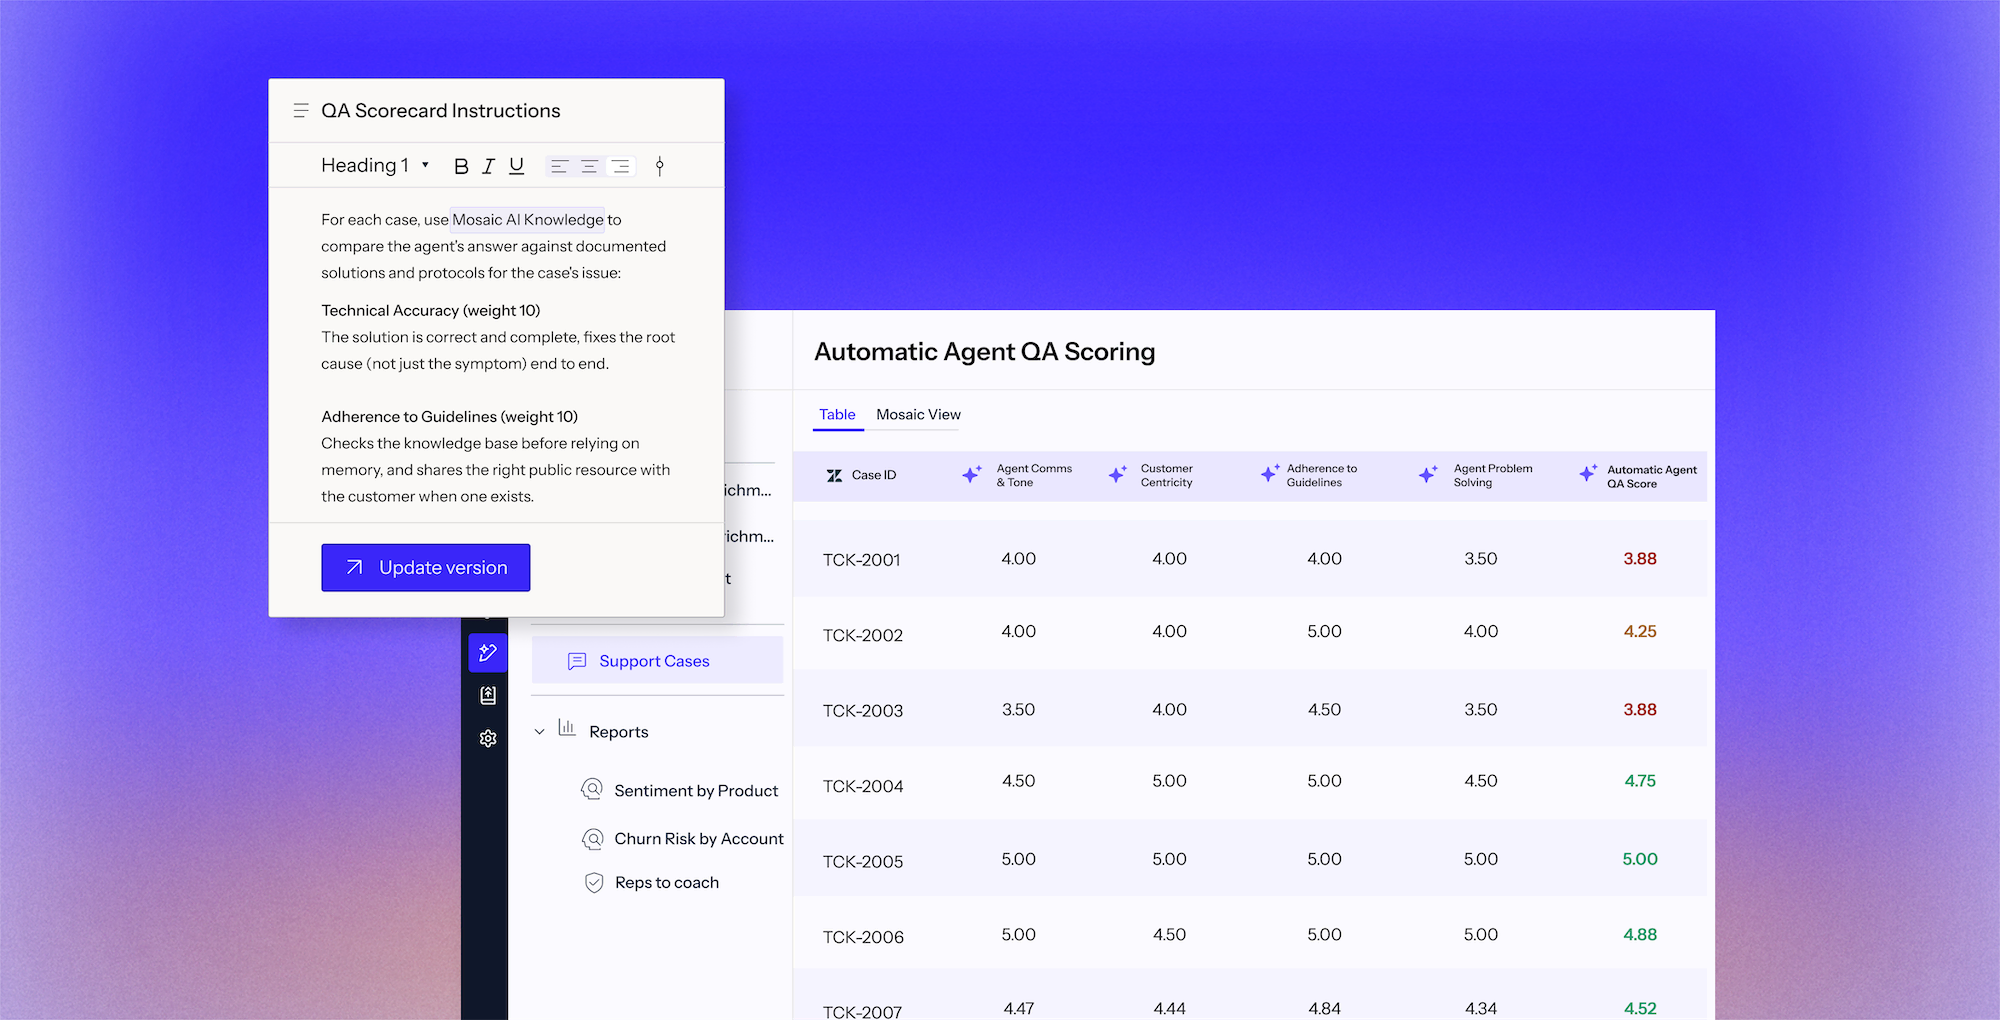
Mosaic AI automatically scores human and AI cases against your standards, with explanations you can drill into.
Scores are organized by product, issue, severity and team to reveal patterns across your queue.
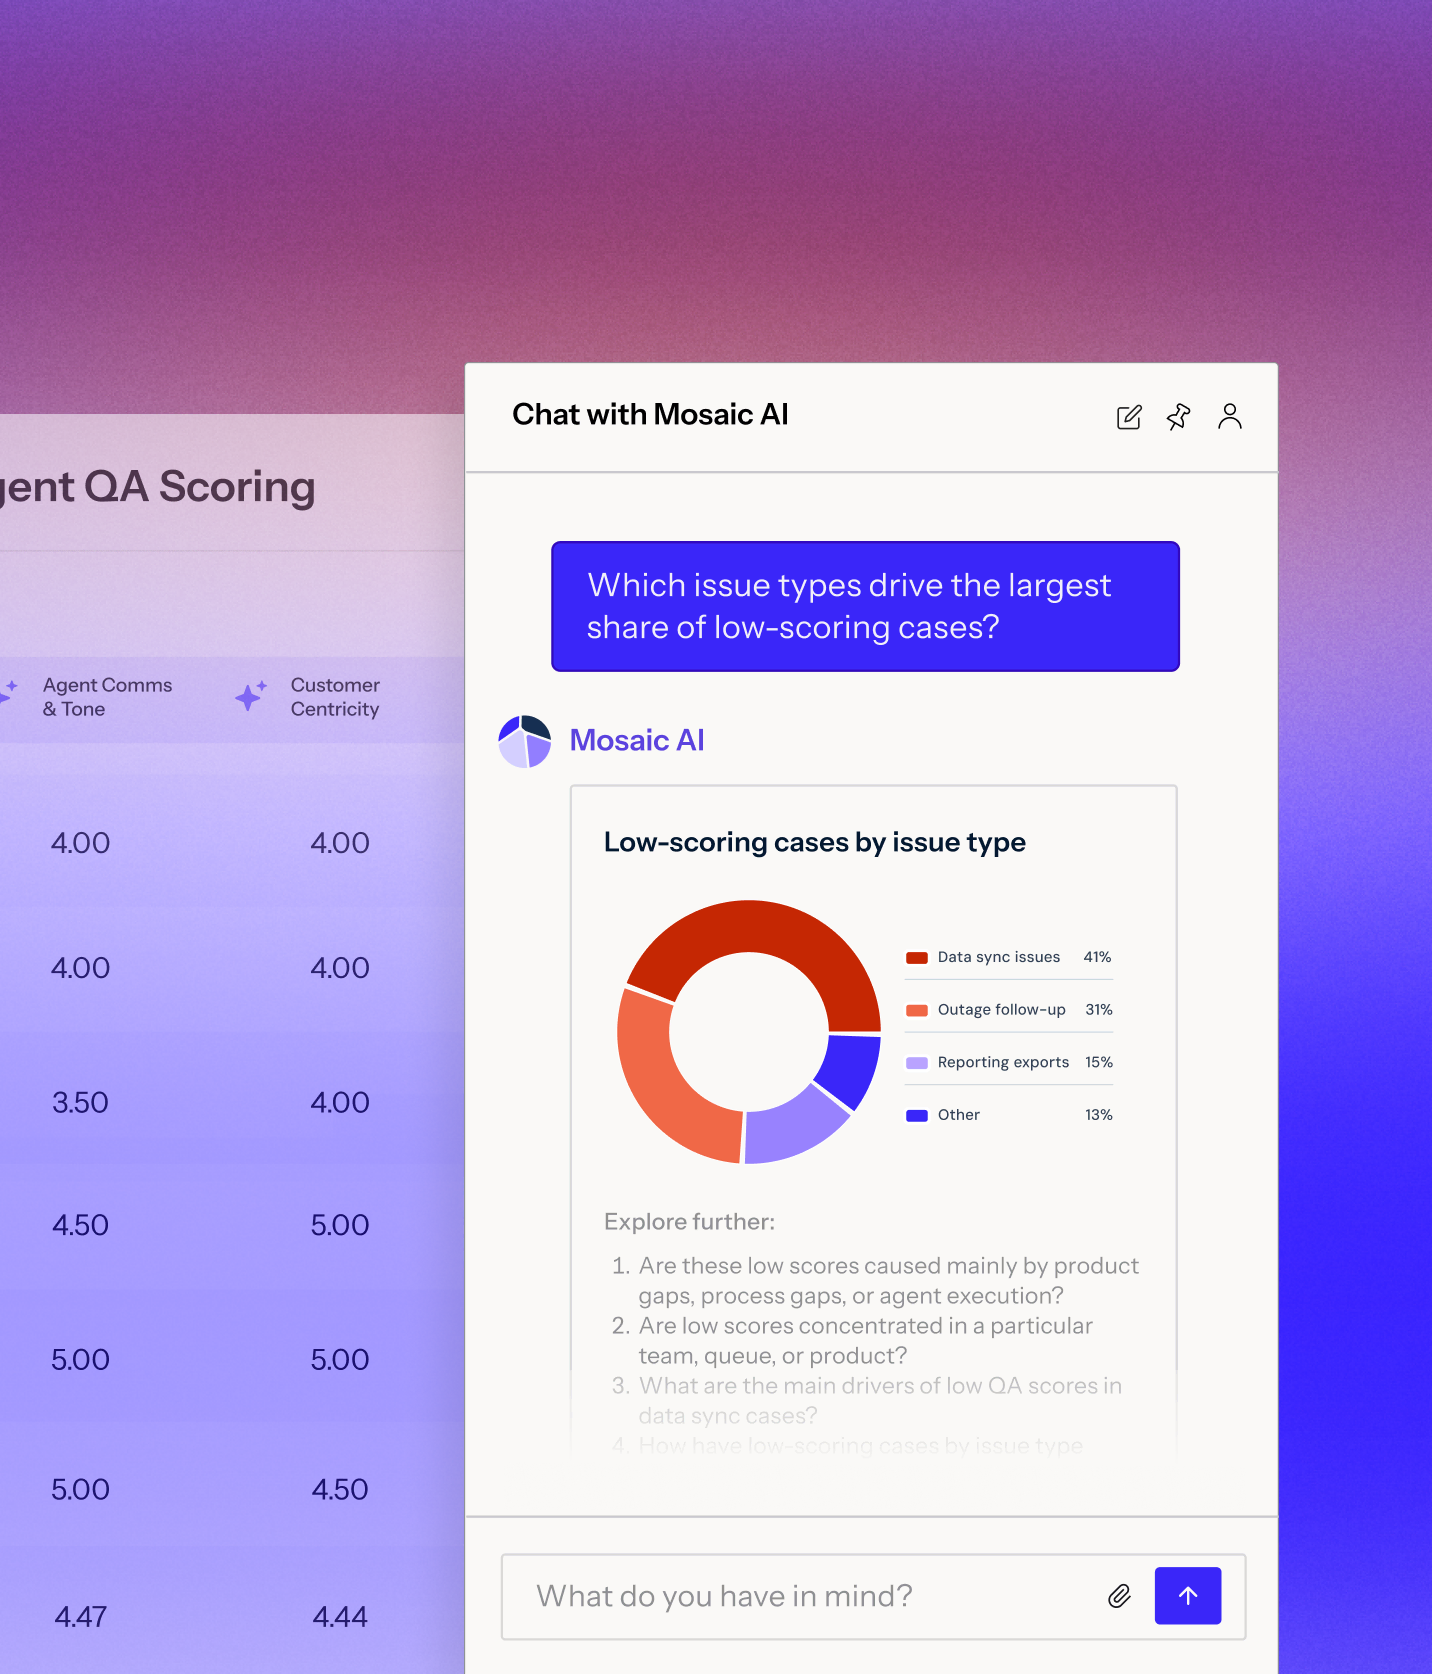
Managers use dashboards and conversational AI to explore results, generate reports on demand and prepare for focused coaching.
“We scaled our Mosaic AI deployment from production pilot to full adoption across multiple business units in under 10 weeks.”
“We see plenty of opportunities where it’s going to help us streamline our customer interactions and make us more efficient and effective.”
“We have been able to scale and keep up with the demands without having to add a significant amount of headcount. With basically the same size team we had last year, we’ve made improvements.”
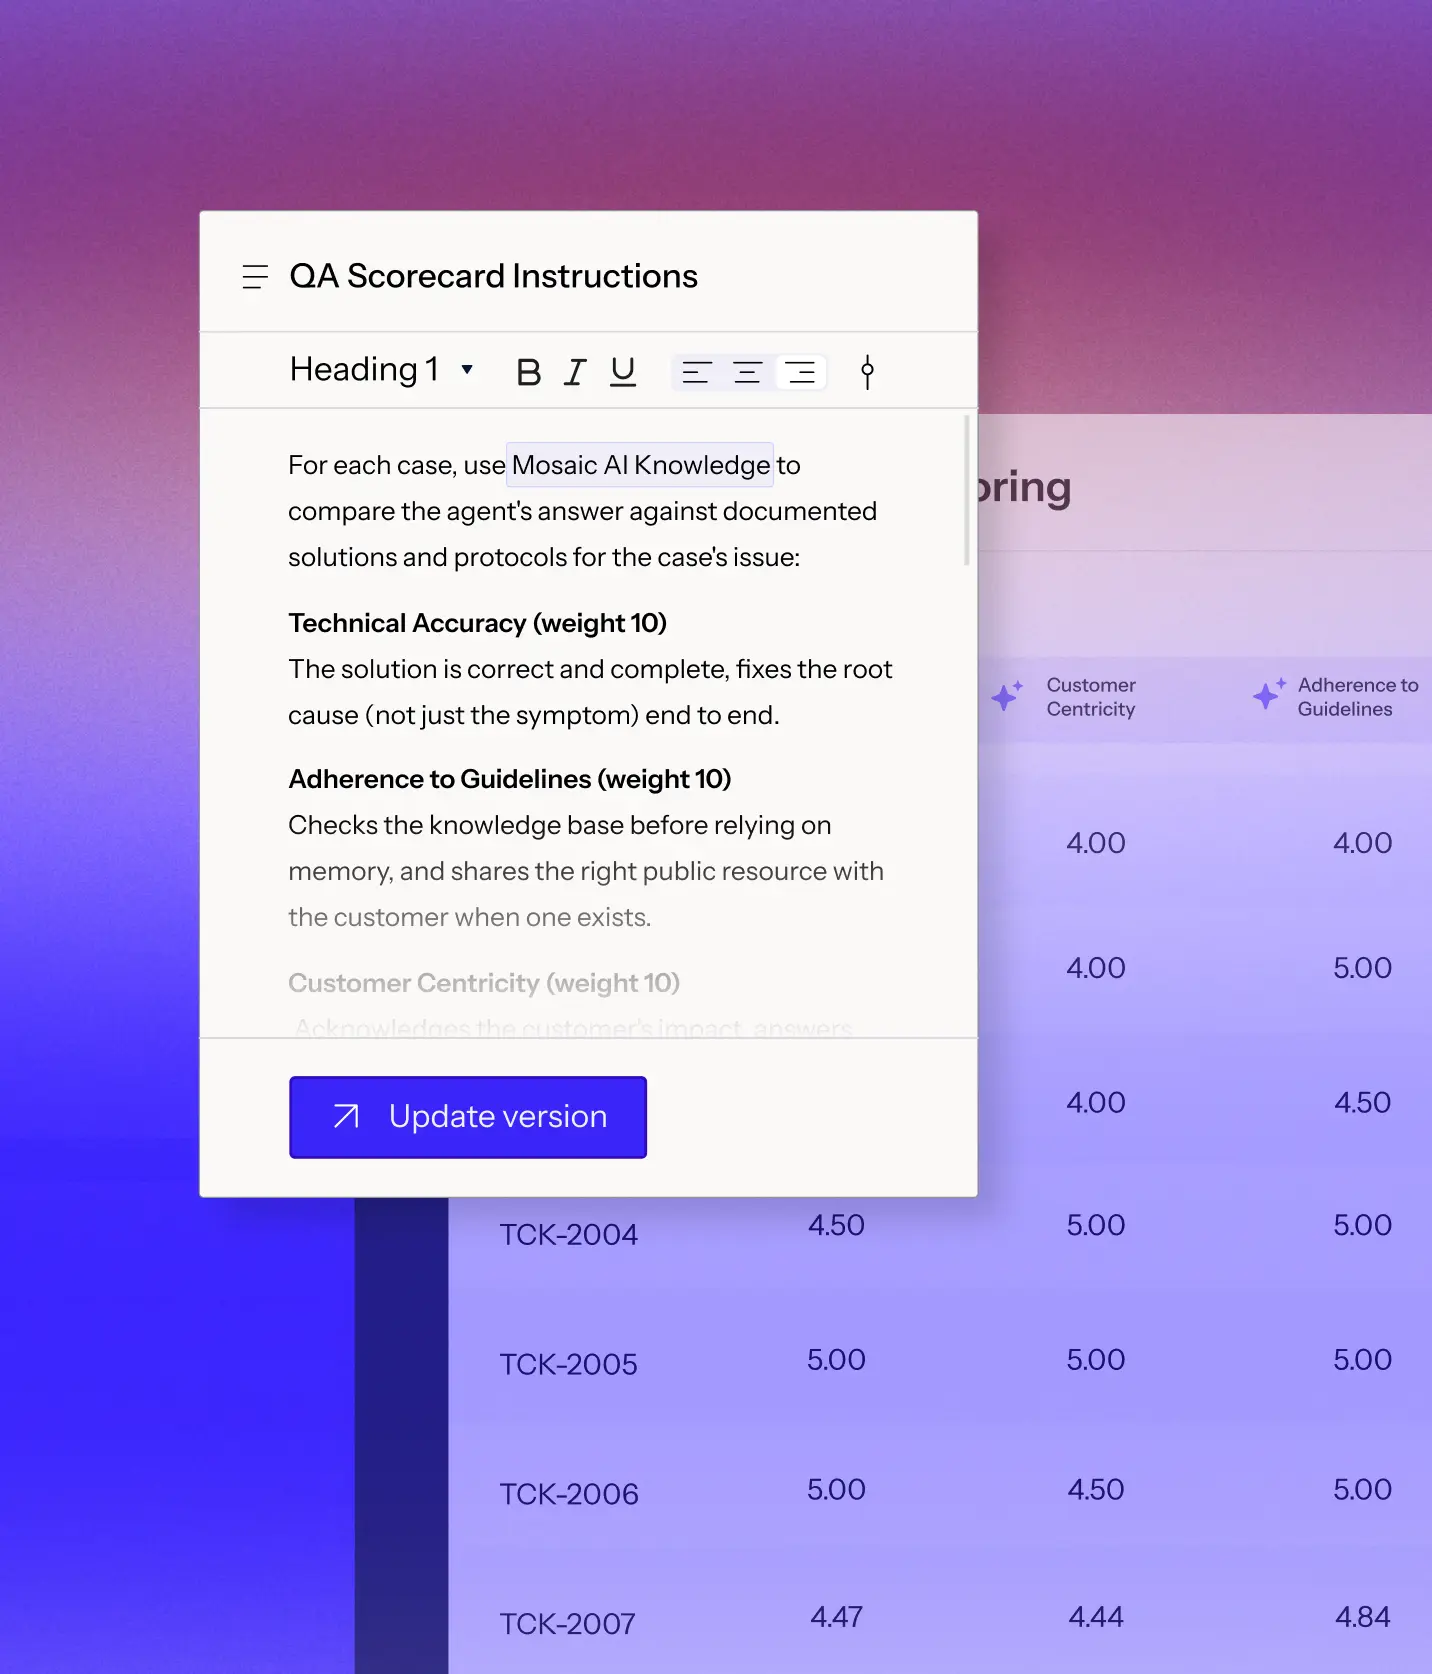
Use your criteria and weightings, with scoring configured around how your team handles cases, whether you have an existing scorecard or documented support standards.
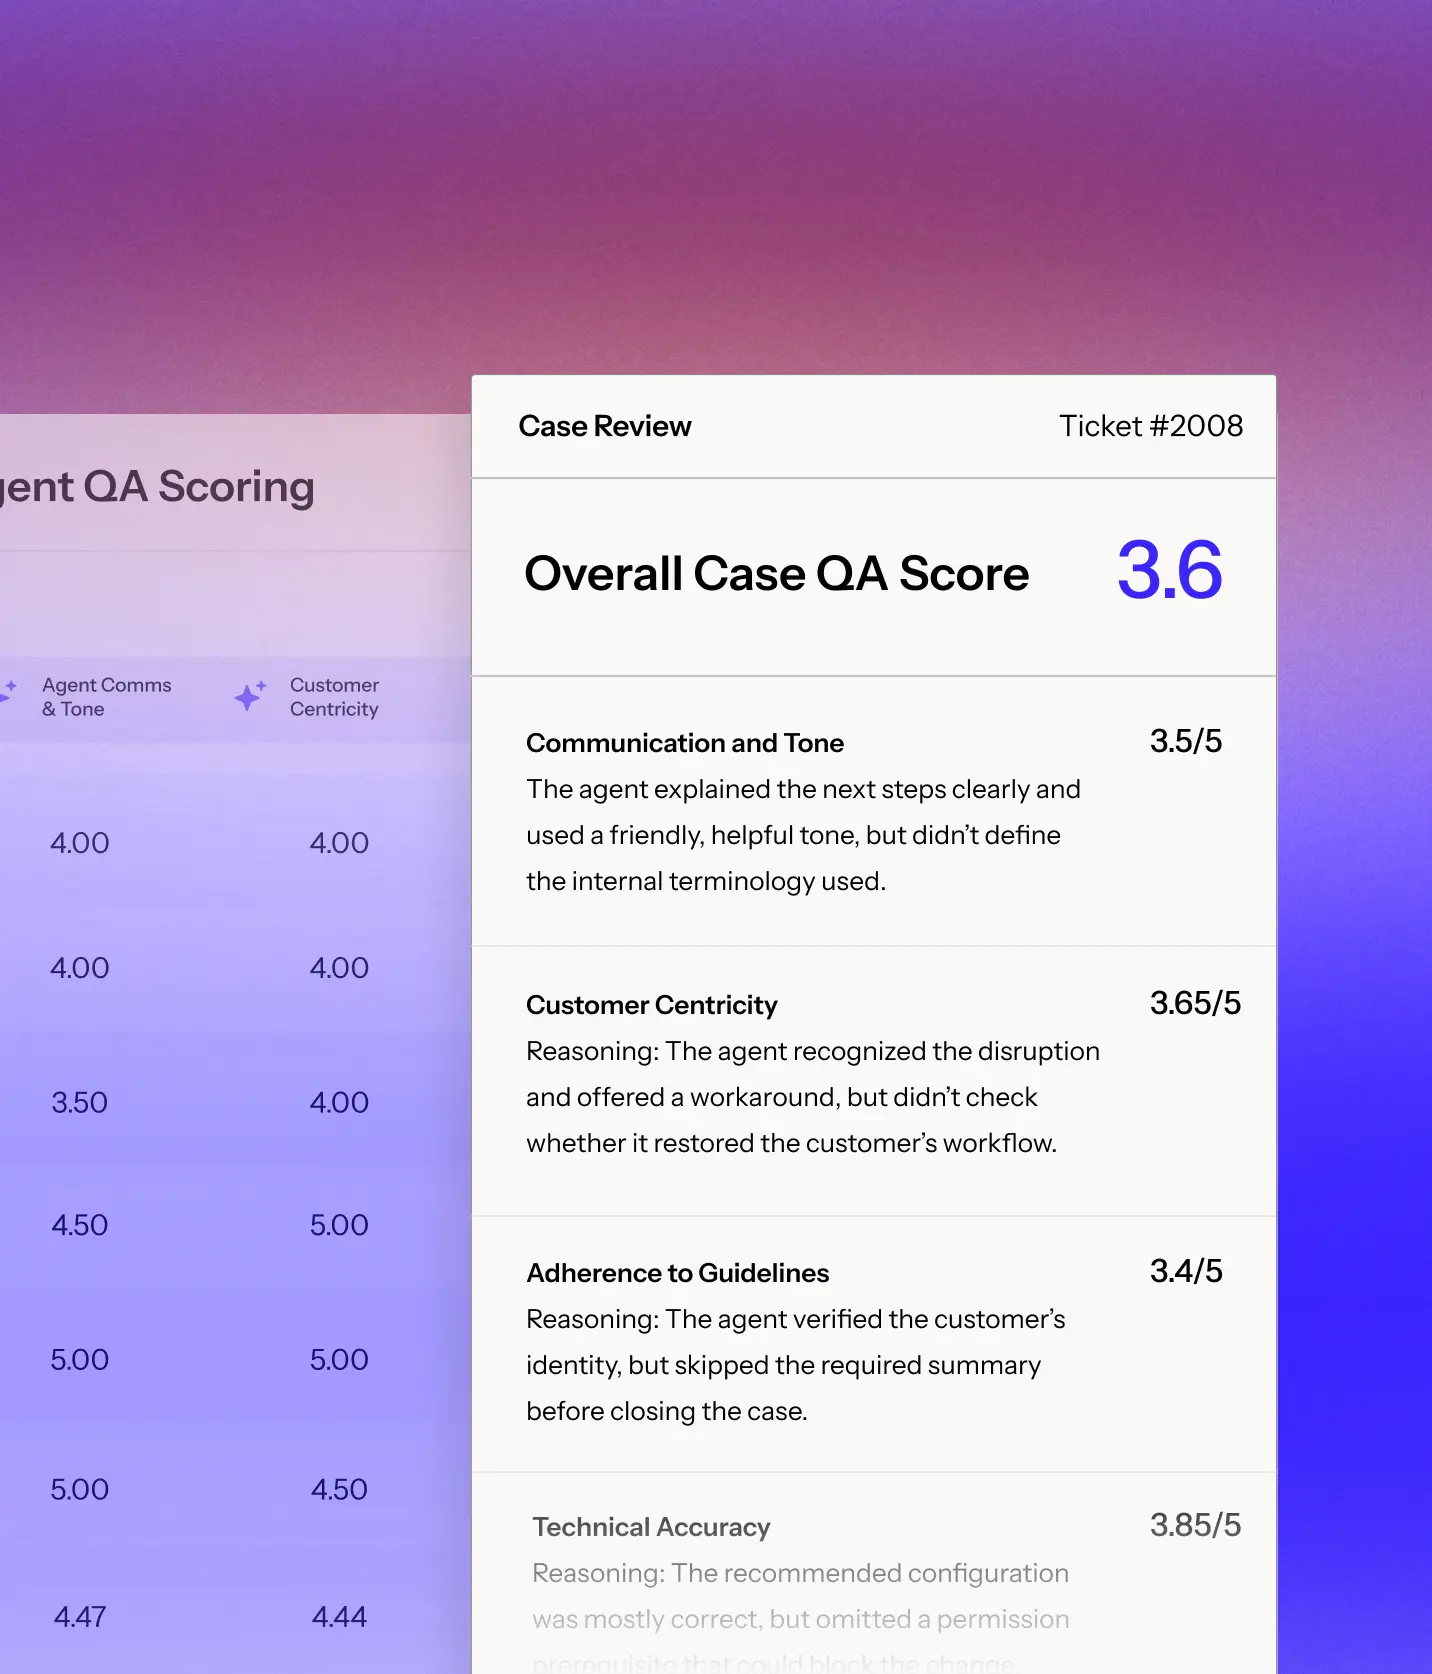
Automatically score every human- and AI-handled case, then drill into the criteria, reasoning, and case history to decide what belongs in a coaching conversation.
Use dashboards and conversational AI to explore quality by product, issue or team and generate reports with specific examples for focused coaching.
Connects to 100+ integrations. Start indexing your full support stack within weeks. No data migration. No engineering required.




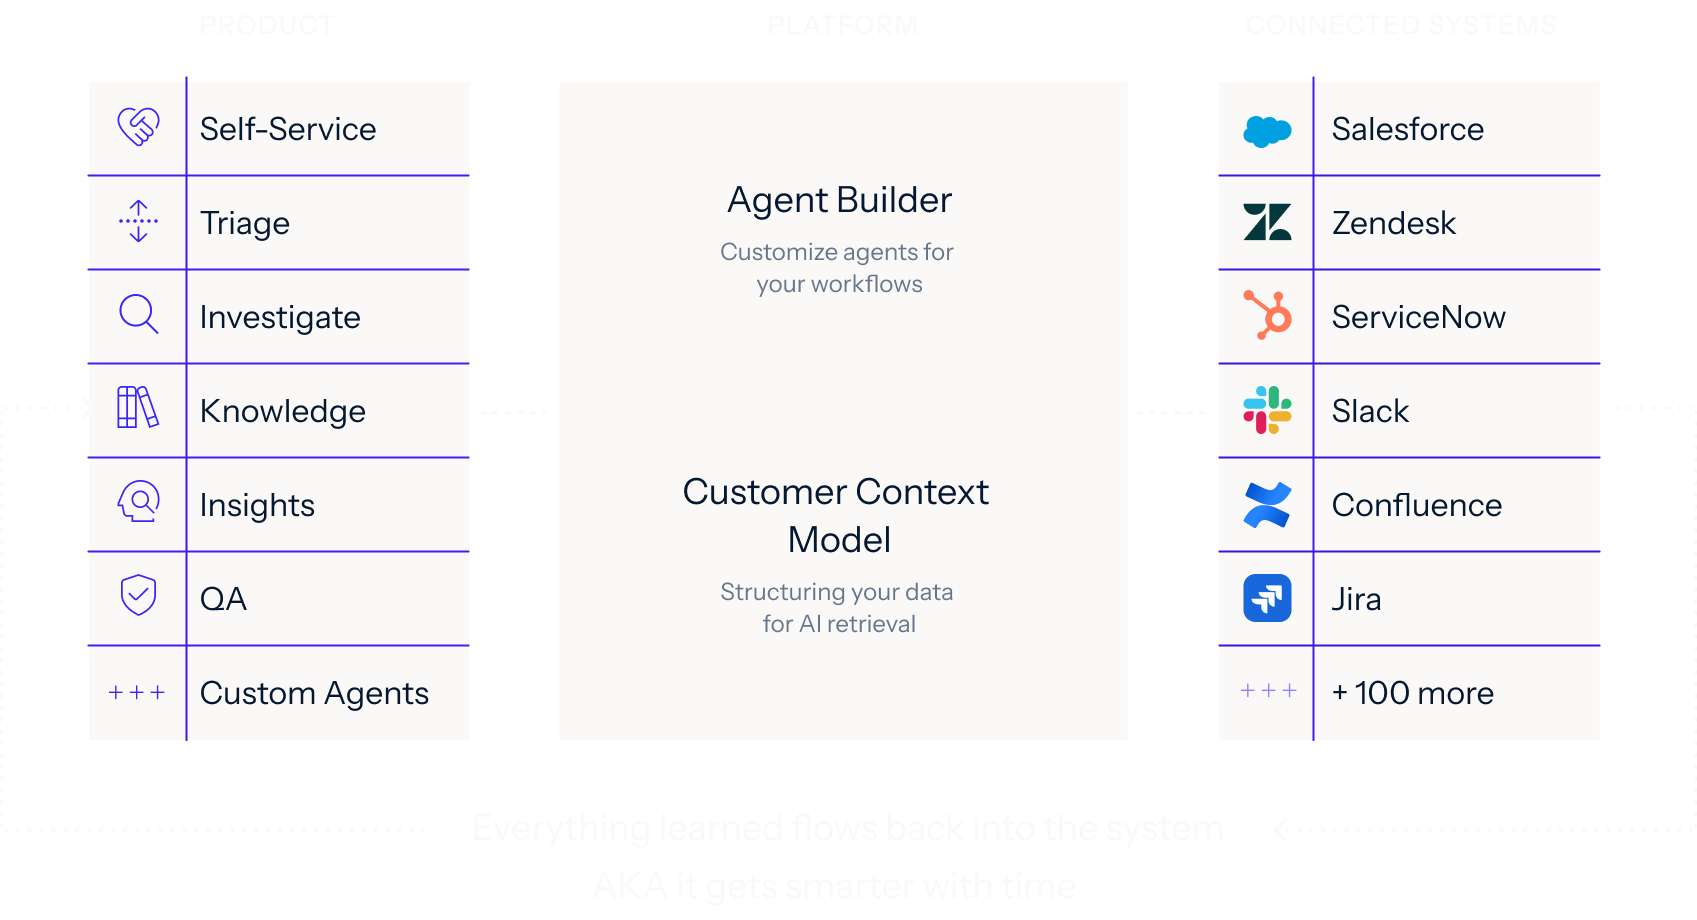
Connect your systems once, then build agents for any workflow on one shared framework. Every agent uses the same data, integrations, and controls, so you can expand without adding another point solution.
Learn more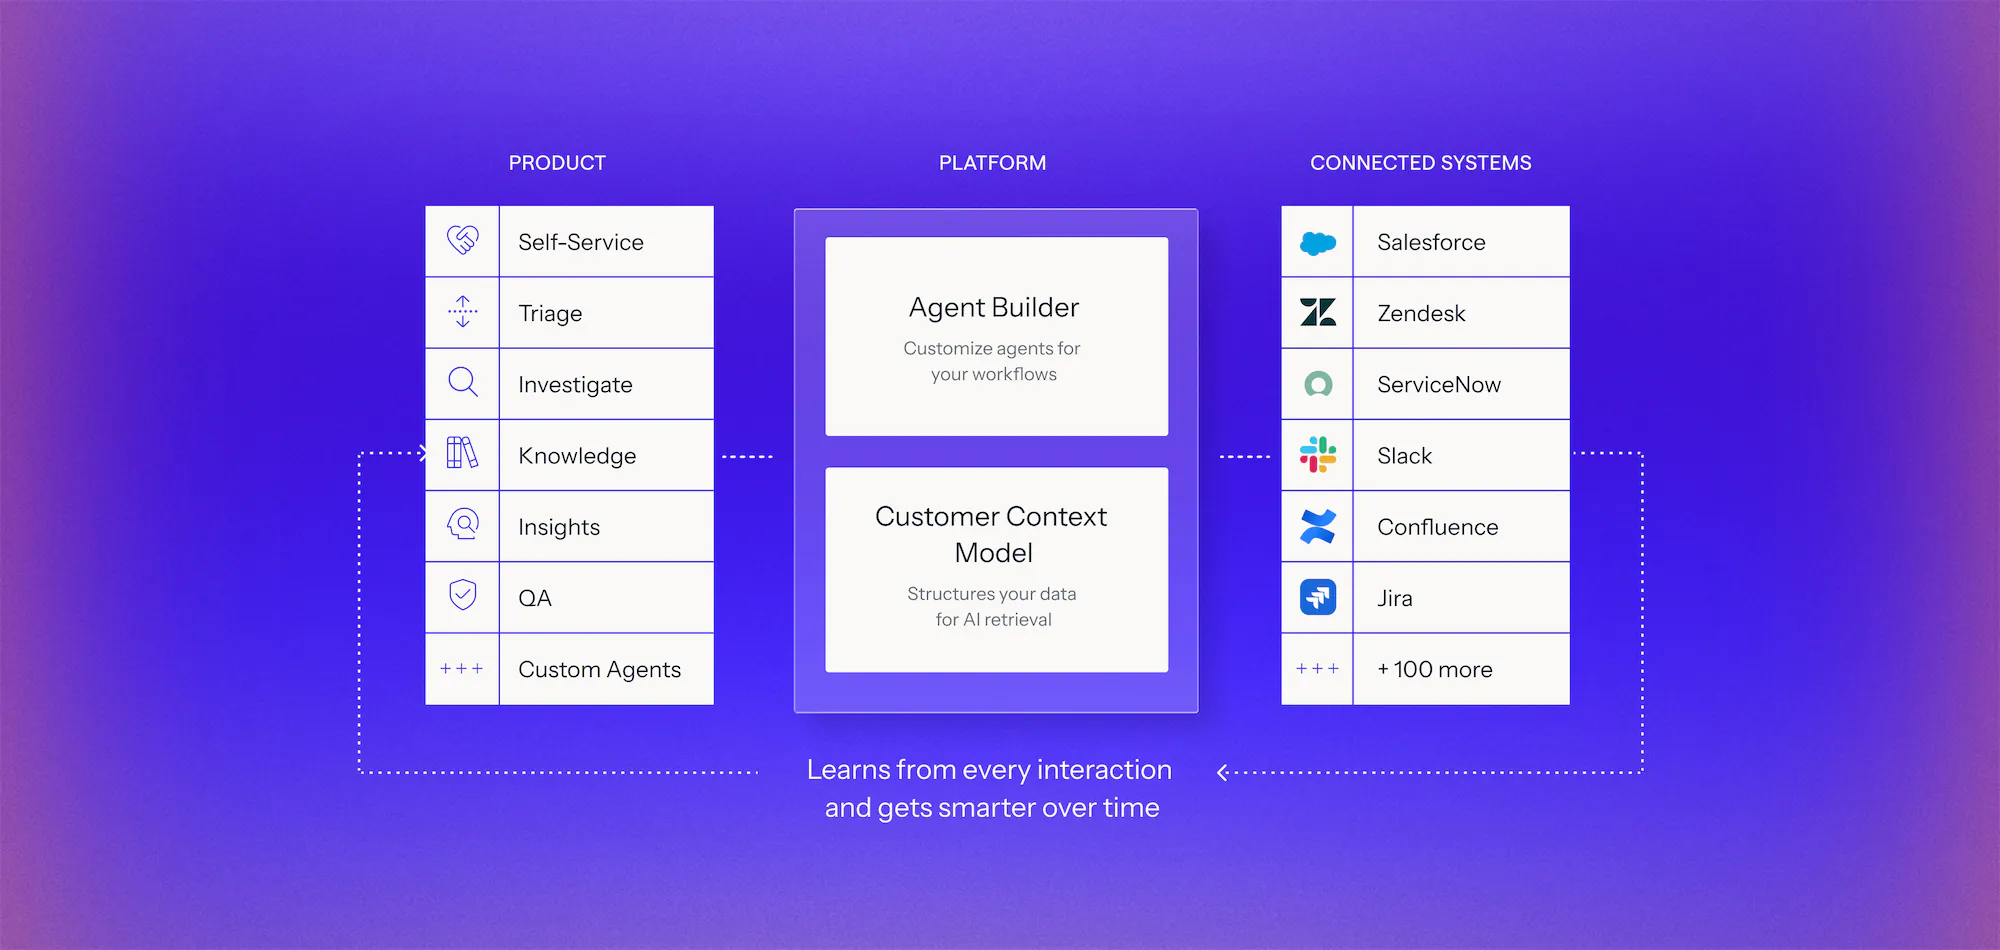
We analyze your real case data, at no cost, to find where time, effort, and spend accumulate, what can be automated, and how much it would lower your cost to serve.
You get a live environment built for your top use cases, running on your own systems, using your own case history. You see the result before you sign anything.
Deployed on top of Salesforce, Zendesk, and the rest of your stack. No migration, no developer resources, deployment expertise included.
Mosaic AI automatically scores every support case, whether a human or an AI agent handled it, against your own quality standards. QA shows where quality is slipping and which cases belong in a coaching conversation.
We work with you to turn your scorecard, documented standards or best-case examples into criteria and weightings Mosaic AI can apply automatically. Each score comes with the reasoning behind it, so you can review your whole queue instead of a small sample.
Scores are organized by product, issue, severity, team and queue, so managers can see where quality drops and pull specific cases to use in coaching.
Mosaic AI checks each answer against the documented solutions in your knowledge base. It scores whether the fix was correct and complete, and whether it addressed the root cause or only the symptom.
AI-handled cases are scored against the same standards as your human team. That lets you track AI agent quality on the same platform as the rest of your queue and decide when agents are ready to take on more.
QA gives managers a consistent score for every case, broken down by criterion with the reasoning attached. They can ask Mosaic AI questions like which issue types drive the most low scores, generate reports on demand, and drill from any trend into the cases behind it. They can update the scorecard as standards change, so scoring keeps up with the team. Instead of spending hours reading sample cases, managers go into coaching with specific examples and a clear reason behind every score.
See what’s hiding in your case data. Mosaic AI applies your support standards to your real cases, at no cost, surfacing quality patterns a handful of reviews can miss, including issues coaching alone can’t fix.